
Summary and Schedule
Workshop Overview
This workshop teaches researchers how to run machine learning and AI work on AWS. It works through the practical decisions, where to store the data, which compute to use, how to launch and monitor a job, and how to estimate and manage the cost.
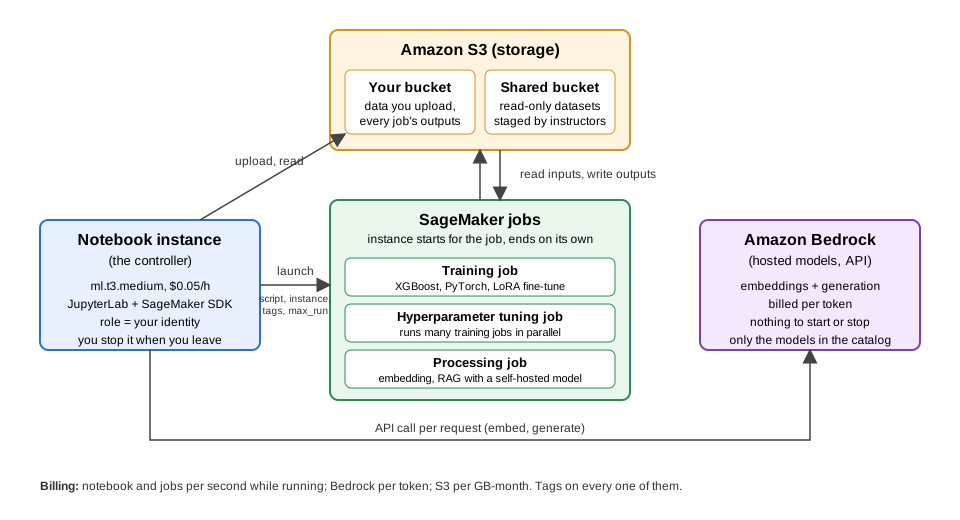
We use Amazon SageMaker to train, fine-tune and run our own models, and Amazon Bedrock to call models AWS hosts through an API. Throughout, we work from a small SageMaker notebook instance that acts as the controller. The demanding work runs on separate instances that SageMaker starts for each job and releases when the job finishes.
The workshop is in four parts, from AWS basics to training, inference and resource management.
The lesson uses four AWS pieces. The overview episode introduces each one in more detail.
Who this workshop is for
Researchers and students who already use machine learning or AI and want to run that work in the cloud. You should be comfortable with Python and Jupyter and know the basics of model training, hyperparameter tuning, fine-tuning, embeddings and RAG. The emphasis is on using AWS, not on teaching those methods. Instructors may review some of them briefly depending on the audience, but the workshop assumes the background. No previous AWS experience is needed.
Cost controls
One of the workshop’s main points is that cloud computing is affordable for research when the resources are chosen and managed with care. Run as written, the exercises cost each learner a few dollars, CPU and GPU training jobs, hyperparameter tuning, a LoRA fine-tune and RAG inference included.
We estimate the cost before launching a job, set a limit on how long it can run, and check its billable time afterwards. Resources are tagged so that spending can be attributed to each learner and project. We also look at how fast the cost grows when a GPU instance is left running or an experiment is scaled up without checking what it needs.
The workshop uses a shared AWS account with restrictions that block the expensive mistakes. The final part looks at those safeguards and how to set the same ones on an account of your own.
What this workshop does not cover
- General ML/AI instruction. The focus is on running existing ML and AI workflows on AWS, not on teaching the algorithms.
- Model deployment. We do not deploy trained or fine-tuned models as always-on inference endpoints. A model trained elsewhere, on a campus cluster say, can still be used here. Upload its weights to S3 and run inference over a dataset as a Processing job, which is what the RAG with Processing Jobs episode does with an open-weight model. Serving it to an application behind an endpoint is the part the lesson leaves out, and the RAG overview says when that is the right tool.
- AI agents and tool use. We do not cover agent frameworks or applications that let a language model call external tools.
If there is another ML or AI workflow you would like to see covered, we welcome suggestions. Open an issue on the lesson GitHub or email endemann@wisc.edu.
| Setup Instructions | Download files required for the lesson | |
| Duration: 00h 00m | 1. Overview: ML on AWS |
When is cloud compute the right tool for a researcher who already has a
cluster or a workstation? What do SageMaker and Bedrock add on top of renting a machine? |
| Duration: 00h 15m | 2. Data Storage: Setting up S3 |
How can I store and manage data effectively in AWS for SageMaker
workflows? What are the best practices for using S3 versus EC2 storage for machine learning projects? |
| Duration: 00h 35m | 3. Notebooks as Controllers |
How do you set up and use SageMaker notebooks for machine learning
tasks? How can you manage compute resources efficiently using SageMaker’s controller notebook approach? |
| Duration: 00h 55m | 4. Accessing and Managing Data in S3 with SageMaker Notebooks |
How can I load data from S3 into a SageMaker notebook? How do I monitor storage usage and costs for my S3 bucket? What steps are involved in pushing new data back to S3 from a notebook? |
| Duration: 01h 25m | 5. (Optional) Pushing Your Notebooks to GitHub from SageMaker |
How can I put the code I write on a SageMaker notebook instance under
version control on GitHub? How do I authenticate to GitHub from a notebook instance without leaving a password or key behind? How can I convert notebooks to .py files and keep
.ipynb files out of version control?
|
| Duration: 02h 00m | 6. Training Models in SageMaker: Intro |
What are the differences between local training and SageMaker-managed
training? What is a SageMaker training job, and what does it cost? How do you estimate what a training job will cost before launching it, and check what it cost afterwards? |
| Duration: 03h 05m | 7. Training Models in SageMaker: PyTorch Example |
When should you consider using a GPU instance for training neural
networks in SageMaker, and what are the benefits and
limitations? How does SageMaker handle data parallelism and model parallelism, and which is suitable for typical neural network training? |
| Duration: 03h 55m | 8. Hyperparameter Tuning in SageMaker: Neural Network Example |
How can we efficiently manage hyperparameter tuning in
SageMaker? How can we parallelize tuning jobs to optimize time without increasing costs? |
| Duration: 04h 55m | 9. Fine-tuning a Vision-Language Model with Training Jobs |
When is fine-tuning worth it? What does a fine-tuning run cost, and how do I estimate that before launching it? How do I fine-tune a model as a SageMaker training job? How do I tell whether the fine-tune helped? |
| Duration: 07h 55m | 10. Overview of RAG Workflows on AWS |
What is Retrieval-Augmented Generation (RAG)? What are the four ways to run inference on AWS, and which does a RAG pipeline need? Why is Bedrock the default, and when is SageMaker the right choice instead? How do the billing models differ, and what does it cost to forget to shut something down? |
| Duration: 08h 10m | 11. RAG with Bedrock |
How do we build a complete RAG pipeline on AWS without provisioning a
GPU? How do we turn a collection of PDFs into retrievable, citable chunks stored in S3? How do we call Bedrock-hosted embedding and generation models so that the spend is tagged to our project? |
| Duration: 09h 00m | 12. RAG with Processing Jobs |
When does a RAG pipeline need a self-hosted, open-weight model instead
of Bedrock? How do we run the embedding and generation steps of the WattBot pipeline as SageMaker Processing jobs that end on their own? How do we pass data in and out of a job through S3, and tag the job so its cost is traceable? |
| Duration: 09h 50m | 13. (Optional) RAG with a Notebook GPU |
How can we run a basic Retrieval-Augmented Generation (RAG) pipeline
entirely from a single GPU-backed SageMaker notebook? How do we go from cached text chunks to a searchable embedding space using a self-hosted model? How can we generate WattBot-style answers (including citations and evidence) that follow the competition’s scoring conventions? |
| Duration: 10h 35m | 14. (Optional) The Same Jobs from the Terminal |
What does the AWS command-line interface (CLI) let me do that the
lesson’s notebooks did, and what should I not do with it? How do I see, and stop, everything that is costing money from a terminal? What request does the SageMaker SDK send when I call estimator.fit()?
|
| Duration: 11h 05m | 15. Resource Management and Monitoring |
How can I monitor and manage AWS resources to avoid unnecessary
costs? What steps are necessary to clean up SageMaker and S3 resources after the workshop? What best practices can help with efficient resource utilization? |
| Duration: 11h 40m | Finish |
The actual schedule may vary slightly depending on the topics and exercises chosen by the instructor.
Setup (Complete Before The Workshop)
Before the workshop:
- GitHub Account (optional) – Only needed for the optional episode on pushing your own code to GitHub.
- AWS Access – Use a shared AWS account (UW-Madison) or an AWS account of your own. On your own account there is no instructor behind the scenes, so you also create the notebook role and stage the datasets that the fine-tuning and RAG episodes read, which the instructor pages describe.
- Data – Download one small zip.
- Glossary — Skim the workshop glossary.
- Episodes 1 to 4 first — They create the bucket and notebook instance every later episode uses.
Details on each step are outlined below.
1. GitHub Account (optional)
Only needed for the optional episode on pushing your notebooks to GitHub. Sign up if you plan to do it.
2. AWS Account
There are two ways to get access to AWS for this lesson. Please wait for a pre-workshop email from the instructor to confirm which option to choose.
Whoever prepares the account: instructors, or you on your own
Whichever tab applies, someone has to prepare the account before the first episode that needs it. On the shared account that is the instructor. On an account of your own, it is you, and the same pages apply. Two things are required on any account:
-
The notebook role. Every notebook and job runs as
ml-sagemaker-use, with the Bedrock permissions the RAG episodes need. The Account preparation checklist has the commands under The notebook role and Bedrock. The checklist also covers GPU quotas, which take weeks on a new account, and the guard rails, which are policies attached to the account and are optional when you are the only user. -
The staged datasets. The fine-tuning and RAG
episodes read the Badger Scribe pages, the CHURRO-3B weights and the
WattBot papers from a bucket somebody filled in advance. The Shared data bucket page has the
commands. On your own account, fill a bucket of your own and set
shared_bucketin those episodes to its name.
The Instructor Notes index has the rest, including the end-of-workshop cleanup.
Once your AWS account is set up, log in to the AWS Management
Console. For the shared account that means the sign-in link
from your instructor’s email, of the form
https://<org>.awsapps.com/start/#/console?account_id=...&role_name=...;
for your own account, the regular console sign-in at
https://console.aws.amazon.com/.
3. Download the Data
- Download data.zip (Right-click -> Save as).
- Extract it (Right-click -> Extract all on Windows; double-click on Mac).
- Keep the two Titanic files somewhere you can find them during the S3 episode, e.g.
~/Downloads/data/titanic/titanic_train.csv~/Downloads/data/titanic/titanic_test.csv
4. Review the Workshop Glossary Page
Skim the Glossary before the workshop (it is also in the top menu of every lesson page); the terms come up from the first episode.
5. Episodes 1 to 4 come first
Do episodes 1 to 4 before anything else. Episode 2 creates your S3 bucket, episode 3 creates the notebook instance and clones the lesson onto it, which is where every later episode’s notebook comes from, and episode 4 is the first read of your bucket from the notebook.
After that, do episodes 6 to 8 in order, since 8 needs the files 7 saves. Episode 9, the fine-tune, stands on its own. Episodes 10 to 13 also go in order, since each reuses what the one before cached in your bucket.